

How Serverless Orchestration Powers Modern Cloud Applications
August 21, 2026
Cost-effective caching: swapping ElastiCache for managed Redis on Hetzner
August 31, 2026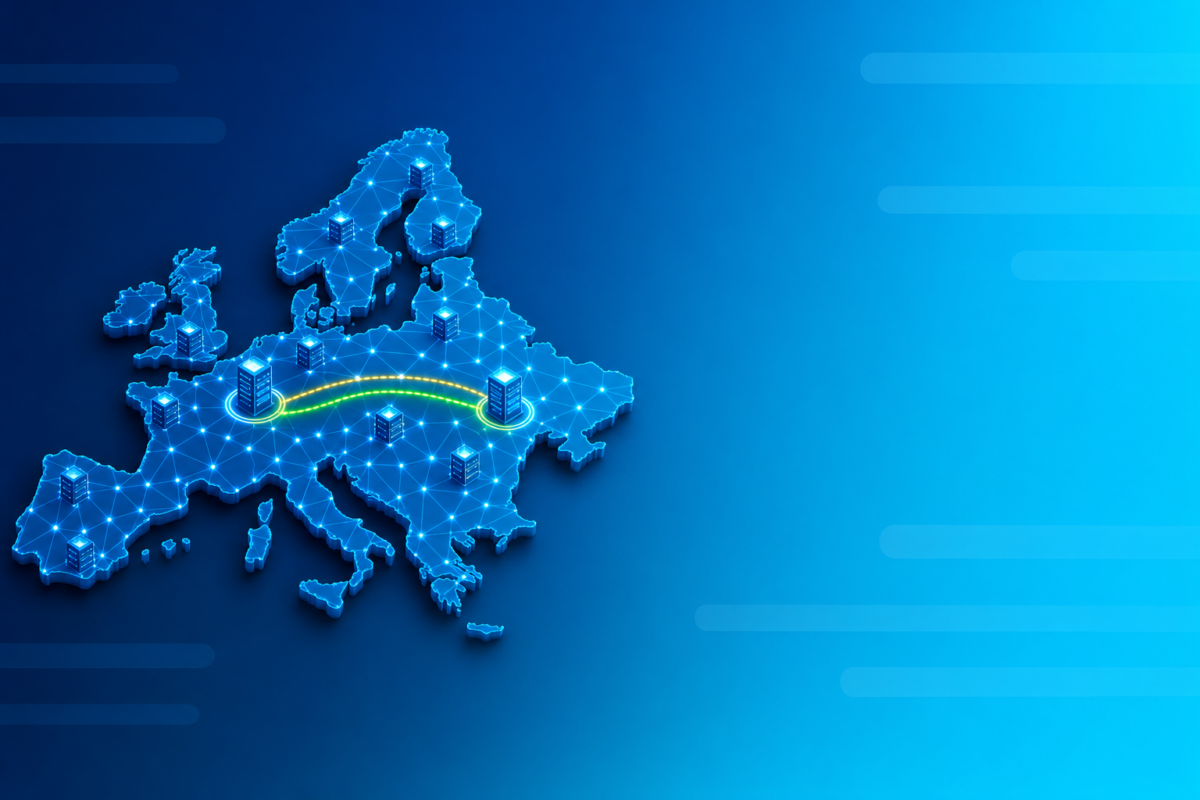
A single data center is a single point of failure. It doesn’t matter how well you provision it – power events, network partitions, cooling failures and the occasional fire have all taken European facilities offline. If your web application serves real traffic and revenue, the question isn’t whether you need availability zones and multiple regions, it’s how to combine them without paying for capacity you never use or building something too complex to operate.
This article maps out the patterns we use to build resilient, multi-region web clusters on European infrastructure – specifically OVHcloud, Scaleway and Hetzner – and where open source fills the gaps that managed hyperscaler services usually cover. It’s written for architects and platform engineers who already know what a load balancer does and want concrete choices, not a glossary.
What the European providers actually give you
Before you design anything, you need to know the failure domains each provider exposes. They are not the same, and the differences change your architecture.
OVHcloud runs two kinds of regions. Its 3-AZ region in Paris gives you three separate availability zones with independent power and network and very low latency between them – the classic setup for synchronous replication and a load balancer spread across zones. Most other OVHcloud regions (Roubaix, Gravelines, Frankfurt, Beauharnois and others) are 1-AZ regions: a single availability zone, but built with 2N+1 redundant power and network and spread across multiple physical data centers. All regions connect over OVHcloud’s own backbone, which matters when you replicate between them. Practically, this means you get true multi-AZ design in Paris today, and geographic separation everywhere else by combining regions like Roubaix and Gravelines.
Scaleway is the most zone-friendly of the three for web workloads. It runs regions in Paris, Amsterdam and Warsaw, each with three availability zones (PAR1/PAR2/PAR3, AMS1/AMS2/AMS3, WAW1/WAW2/WAW3), plus a single-zone region in Milan (MIL1). That gives you real intra-region redundancy in three countries and clean cross-border separation – Paris and Warsaw sit in different jurisdictions and different power grids, which is useful for both resilience and data residency arguments.
Hetzner is priced for density rather than zone isolation. Its European footprint is the eu-central network zone, covering Falkenstein and Nuremberg in Germany and Helsinki in Finland. There’s a catch that shapes your design: private Networks, Floating IPs and Load Balancers must stay within a single network zone, and Load Balancers must be in the same network zone as their targets. So within eu-central you can spread instances across Falkenstein, Nuremberg and Helsinki behind one load balancer, but a second European “region” in Hetzner terms means running a parallel stack and handling cross-zone routing yourself.
Three tiers of resilience, and what each costs you
Resilience isn’t one decision. It’s a set of them, and each tier adds cost and operational weight. Pick the highest tier your recovery objectives actually justify.
Multi-AZ inside one region
This is the baseline for any serious web application and it should be non-negotiable. Run your web and application tier across at least two availability zones, put a load balancer in front, and use a managed database with a standby in a second zone.
On Scaleway you spread instances across PAR1 and PAR2 behind a Load Balancer and use Managed Database for PostgreSQL or MySQL with high availability enabled, which keeps a synchronous standby and promotes it automatically on failure. On OVHcloud’s Paris region you do the equivalent across its three AZs. On Hetzner you place servers in Falkenstein and Nuremberg behind a Load Balancer within eu-central and run your own database replication, since Hetzner has no managed relational database – more on that below.
What this protects against: a single availability zone failing. What it doesn’t protect against: a whole region going dark, or a bad deploy that corrupts data in every zone at once. Latency between zones in a region is typically a millisecond or two, so synchronous replication is fine here.
Active-passive across two regions
The next step is a warm standby in a second region. Your primary region serves all traffic. The secondary region runs a smaller version of the stack, receives asynchronous database replication, and can be promoted when the primary is unreachable.
This is where cross-region replication and DNS failover come in. You replicate the database asynchronously (Scaleway Paris to Warsaw, or OVHcloud Roubaix to Gravelines), keep object storage in sync, and point a health-checked DNS record or a global anycast entry at the primary. When the primary fails a health check, you promote the standby database and flip DNS or your edge routing to the secondary.
The honest tradeoff: asynchronous replication means a non-zero recovery point objective. If the primary dies, you may lose the last few seconds of writes. DNS failover also isn’t instant – TTLs and resolver caching mean real users can see errors for a minute or more. Budget for both in your RPO and RTO numbers rather than pretending failover is seamless. It isn’t.
Active-active across regions
Active-active – both regions serving live traffic at once – is the most resilient and by far the most expensive to build and reason about. You need either a database that tolerates multi-region writes or a strict data-partitioning scheme, plus conflict handling, plus session affinity or fully stateless sessions. Most web applications don’t need this, and many that adopt it would have been better served by solid multi-AZ plus active-passive. Reach for it when a region-sized outage is genuinely unacceptable and you have the engineering time to operate it. Otherwise the complexity is a liability, not a safeguard.
Replacing the hyperscaler components
The hard part of leaving a hyperscaler is rarely the compute. It’s the managed services stitched around it. Here’s how the pieces map onto European providers and open source.
The database
This is the component that decides your resilience story. Scaleway and OVHcloud both offer managed PostgreSQL and MySQL with high-availability options that keep a hot standby and handle promotion for you – the direct equivalent of a multi-AZ managed database, and the sensible default. You get automated backups, minor version patching and provider-managed failover without running the plumbing yourself.
Hetzner has no managed database, which is the price of its low cost. You run it yourself, and the standard open source answer is Patroni with PostgreSQL: Patroni handles leader election and automatic failover using etcd or Consul for consensus, and you front it with HAProxy or PgBouncer. It works well and it’s what many teams run in production, but you own patching, backups and testing the failover path. Whatever you choose, verify the promotion actually works under load before you depend on it, not during your first real outage.
Object storage
All three providers offer S3-compatible object storage – Scaleway Object Storage, OVHcloud Object Storage and Hetzner Object Storage – so application code written against the S3 API usually needs only endpoint and credential changes. For cross-region durability, set up bucket replication or run a scheduled sync so your standby region has current assets. If you want provider independence at the storage layer, MinIO gives you a self-hosted, S3-compatible option you can run across your own nodes, though then you’re responsible for its durability rather than the provider.
The CDN and edge
A content delivery network is what absorbs traffic spikes and keeps static assets close to users, so it’s part of your availability picture, not just performance. OVHcloud and Scaleway both offer CDN products backed by European points of presence. If you’d rather own the edge, put Varnish or an Nginx caching tier in each region, or use bunny.net or Fastly as a provider-neutral CDN layer in front of your origins. The pattern that matters: cache aggressively at the edge so an origin or even a whole region can wobble without every user noticing.
Load balancing and traffic distribution
Inside a region, use the provider load balancer – Scaleway and Hetzner both offer managed ones, and OVHcloud has Load Balancer and Public Cloud options. Across regions, the provider load balancer stops at the region or network-zone boundary, so you need a layer above it. Health-checked DNS (from a provider or a self-hosted PowerDNS setup) is the simplest. Anycast, where the same IP is announced from multiple locations, gives faster failover but needs more networking work. Match the mechanism to your RTO – if you promise sub-minute recovery, DNS TTLs alone won’t get you there.
DDoS protection and the web application firewall
OVHcloud includes anti-DDoS protection across its network by default, and Scaleway and Hetzner provide DDoS mitigation as well, which removes one thing you’d otherwise build. For the application firewall layer, ModSecurity or the newer Coraza engine paired with the OWASP Core Rule Set gives you an open source WAF you can run in every region, in front of each origin, with rules you control.
A reference architecture on European infrastructure
Putting it together, a resilient medium-to-large web application on Scaleway might look like this:
- Primary region – Paris. Web and app instances across PAR1 and PAR2, behind a managed Load Balancer. Managed PostgreSQL with high availability, standby in a second zone. Object Storage for user uploads and static assets. Private network isolation between tiers.
- Secondary region – Warsaw. A smaller warm stack across WAW1 and WAW2. PostgreSQL receiving asynchronous replication from Paris. Object Storage kept in sync by scheduled replication.
- Edge. CDN in front of both regions caching static assets, with an open source WAF at each origin.
- Traffic control. Health-checked DNS pointing at Paris, configured to fail over to Warsaw when Paris stops responding.
- Backups. Automated database backups plus periodic snapshots, stored in a different region from the source and restore-tested on a schedule – not just taken and forgotten.
The same shape works on OVHcloud with the Paris 3-AZ region as primary and Gravelines or Roubaix as secondary. On Hetzner you’d run multi-location redundancy within eu-central and, for a true second region, a parallel stack in another provider or zone with your own replication and routing – Hetzner’s economics are excellent, but its network-zone boundaries mean you do more of the cross-region work yourself.
The part most teams get wrong
Failover you haven’t tested is a guess, not a plan. The most common failure we see isn’t a missing standby – it’s a standby that was never promoted successfully, a backup that never restored, or a DNS change nobody had permission to make at 3am. Resilience is an operational property, not an architecture diagram.
So before you call a design highly available, prove it. Kill the primary database and confirm the standby takes over and the application reconnects. Restore a backup into a clean environment and check the data is intact. Trigger a region failover during business hours, with people watching, and measure how long real recovery takes. Keep testing and live environments separate, inventory every dependency before a migration, and make sure any cutover can be reversed. If it can be automated, automate it – a runbook that depends on one person remembering the steps is a single point of failure too.
Building this well on European infrastructure gives you three things at once: resilience that survives a data center or a region, data residency that keeps you inside EU jurisdiction, and a cost base that’s often a fraction of the hyperscaler equivalent. That combination is exactly what ADM Cloudtech designs and runs for medium-to-large web applications – matching the architecture to the software so it stays available, compliant and affordable as it grows. If you’re weighing a move to European infrastructure or hardening what you already run, that’s a conversation worth having before the next outage, not after it.